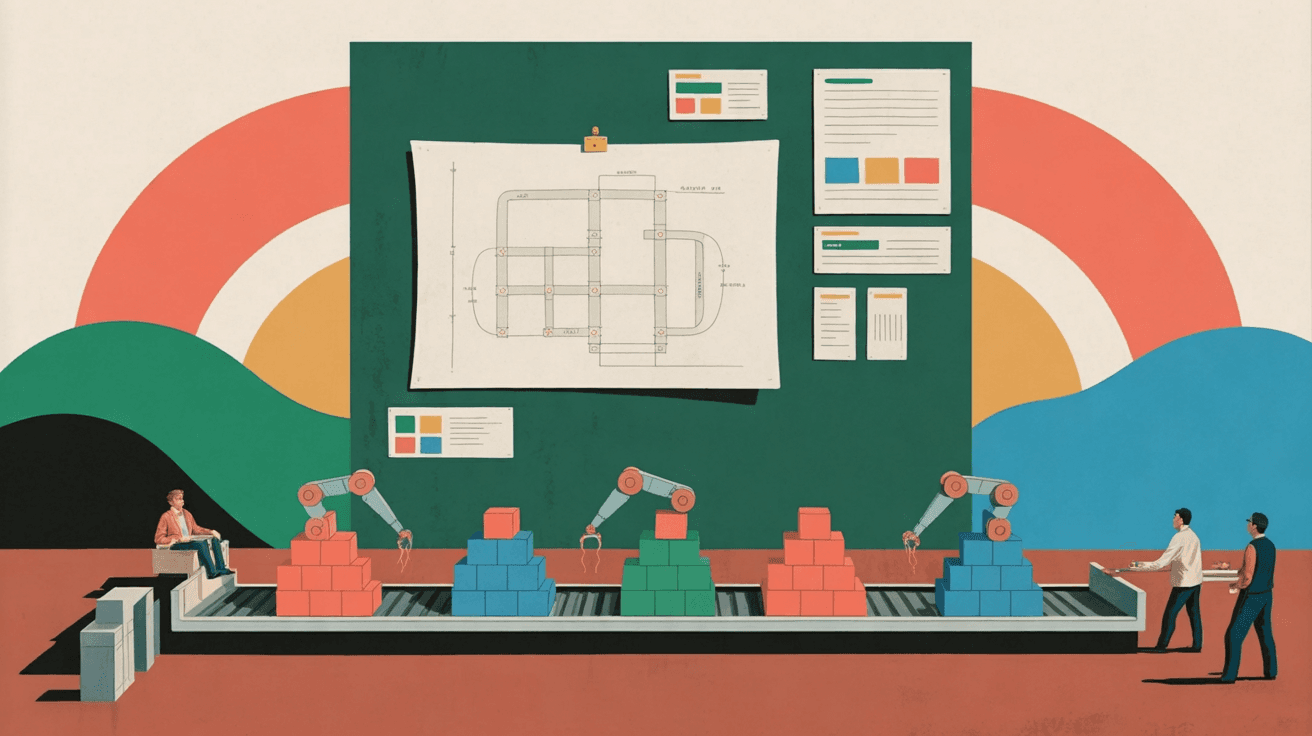
Spec-driven development with AI agents means every piece of work starts as a written spec, and AI agents build against that spec rather than against a chat. In our studio, the spec is a ticket in Linear that says what's wrong or missing, what "done" looks like, the files involved and how we'll check it. Agents build it, run the relevant tests and stop at "pushed". The limits around the agents matter more than the agents themselves.
Here's how that works day to day across four products and a set of client platforms.
Why specs matter more with AI, not less
When a person writes code, a vague ticket gets filled in by their judgement and their memory of last week's conversation. An AI agent doesn't have last week's conversation. It has the ticket.
So the quality of the ticket decides the quality of the work. A clear spec lets an agent build the right thing first time. A vague one gets you a confident, well-structured implementation of the wrong thing, which is worse than nothing because it looks finished.
There's a second reason. Decisions made in a chat window disappear. If a decision needs to outlive the conversation, it goes in the ticket. Six months later, when someone asks why a setting ships switched off or why a report uses a particular exchange rate, the answer is written down next to the work.
What goes in a ticket
A ticket that an AI agent can build from has four parts:
- What's wrong or missing. In plain language, from the user's side.
- What "done" looks like. Acceptance criteria someone can check, not "make it better".
- The files involved. Where the change lives, so the agent doesn't go hunting or touch things it shouldn't.
- How we'll check it. Which tests, which screens, which edge cases.
For a small, obvious fix, that can be two lines. For a feature that touches money, it's longer, and it includes the product decisions: which rate to convert at, where rounding happens, whether the new behaviour starts switched on or off.
If you're writing specs for an AI product yourself, our technical specifications checklist for founders covers the product side in more depth.
Scouting: is the ticket even true?
Not every ticket describes reality. "This is broken" sometimes turns out to be "this was changed last Tuesday". "Add X" sometimes turns out to be "X already exists, under a different name". Specs get written against assumptions that have gone stale.
Building against a false premise is expensive. The agent will happily build something that already exists, or change the wrong function because it has a plausible name.
So when we're genuinely unsure whether a ticket's premise holds, a scout goes first. It's a read-only agent that:
- Pulls the latest code, so it's not looking at a stale copy.
- Reads the code that actually runs, not the function that looks like it might.
- Treats "already built" and "already decided" as real possibilities.
- Comes back with a verdict (ready to build, already done, blocked, or not what the ticket says) and, if it's ready, a build spec.
Only tickets that come back ready get builder time.
We don't scout everything. Small, obvious fixes skip that step and go straight to a builder with a two-line spec. Scouting is for tickets whose premise is genuinely uncertain. Running it on everything would just be a slower way to do the same work.
Builders, with limits
The building is done by AI coding agents working in our codebases through Claude Code. Each one takes a ticket, builds it, runs the relevant tests and stops.
These are the limits we run with, and why.
At most three builders at once
It's tempting to think ten agents get ten times as much done. They don't.
Parallel changes that touch the same shared files (the database schema, validation rules, route indexes) collide. Every collision means one branch has to be reworked, and every rework costs a full re-test. Past a certain point, adding builders adds conflicts faster than it adds output.
We learned this by running more than three at once and watching the rework pile up. Three is where we've settled.
A fixed merge order
When several builders finish, we merge them in a fixed order, and only rebase the remaining branches after each merge. That way each branch is tested against the code it will actually land on, and conflicts get resolved one at a time instead of in a tangle.
Scoped tests while building, the full suite in CI
A builder re-running every test for each small fix is slow and pointless. While building, and during any fix rounds after review, agents run the tests that cover what they changed.
The full suite runs in CI, and CI is the authority. Nothing merges on an agent's say-so.
Stop at "pushed"
A builder's output is the change, not a progress report. Each one stops when its branch is pushed. No polling CI in a loop, no handing work to further sub-agents, no narrating what it's doing, no tidying up code nobody asked it to touch.
One background check watches CI. If something fails, that becomes the next small, scoped piece of work.
Stop when the useful work is done
The same applies to every agent in the system. Once a scout's verdict is in hand, or a builder has pushed, it's finished. Leaving agents running "just in case" costs time and money and adds nothing.
Review on every change
Specs and limits get the code written. Review decides whether it ships.
Every change is reviewed before it ships. Anything touching money, logins, signing or keeping one customer's data away from another's gets an additional adversarial review from a separate, stronger model whose job is to find how it could go wrong. Everything else gets a lighter review once it works. People read the findings and decide.
We cover how that's tiered in reviewing AI-written code that handles money, and why it's the line between this and vibe coding in AI-assisted engineering vs vibe coding.
The flow, end to end
| Step | Who | Output |
|---|---|---|
| Decide what to build | People | A priority |
| Write the spec | People, often drafted with AI | A ticket in Linear |
| Check the premise (only if uncertain) | Scout agent, read-only | Verdict plus build spec |
| Build | Up to three builder agents | A pushed branch with scoped tests passing |
| Full tests | CI | Pass or fail |
| Review | Reviewer, tiered by risk | Findings for a person to judge |
| Merge | In fixed order | Code on the main branch |
| Deploy | Pipeline, about nine minutes | Live, often switched off |
| Launch | People | Feature on, docs and pages updated |
What we've seen
Fast deploys keep specs small. We split Handl's deploy pipeline into parallel jobs, and deploys went from around half an hour to about nine minutes. When deploys are slow, you batch work up, and big batches need big specs that are harder to get right. At nine minutes, each ticket can be small, and small tickets are the ones agents build well.
Shipping and launching are different days. A merged feature can sit in the product switched off until the help docs, the product page and the feature all agree. After something ships, another agent reads what changed and writes the follow-up tickets for the marketing page and the help article. Those follow-ups are specs too.
The discipline is the hard part. Writing a proper ticket takes longer than typing a request into a chat. Holding to three builders when there's a backlog of thirty tickets takes patience. Both pay back many times over in work that doesn't need redoing. The full picture is in how a small studio ships 100+ changes a week.
FAQ
What is spec-driven development with AI?
It's a way of working where every change starts as a written spec with clear acceptance criteria, and AI agents build against that spec. Tests, CI and review then check the result against what was written down.
How detailed does a spec need to be for an AI agent?
Detailed enough that someone else could check the result: what's wrong, what done looks like, which files, and how to verify it. Small fixes can be two lines. Anything touching money needs the product decisions spelled out.
Why limit how many AI agents run at once?
Because parallel changes to shared files collide, and every collision costs rework and a full re-test. We run at most three builders and merge in a fixed order.
Do the AI agents decide what ships?
No. People decide what to build, write and approve the specs, read review findings and choose what launches. CI decides whether tests pass. Agents build.
If you want a product built with AI inside a spec-driven process, that's what we do.
 Consulting Inquiries