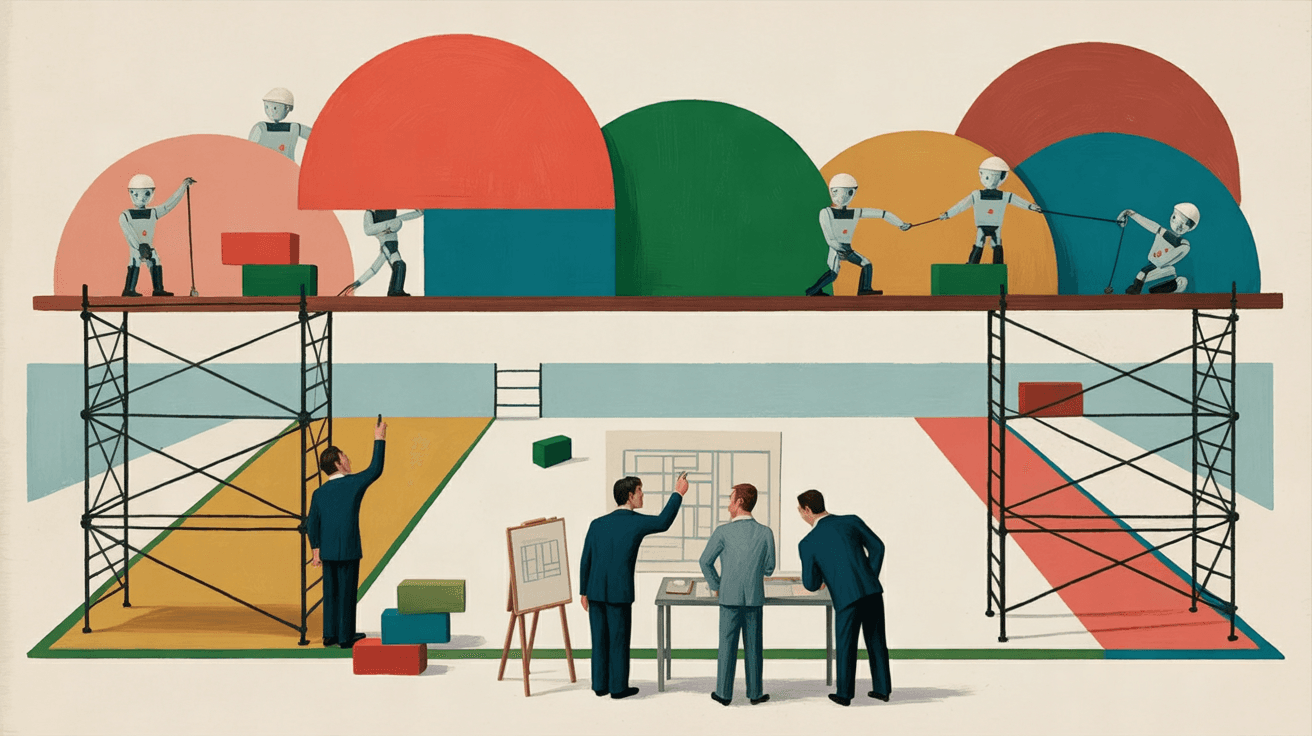
Agentic engineering is software engineering where AI agents carry out the work end to end, from reading a ticket to pushing a tested branch, and the people's job shifts to setting the intent, the limits and the checks. It's not autocomplete, where a person types and the AI suggests. It's not vibe coding, where a person prompts and ships whatever comes back. The agents do tasks. The engineering is in everything wrapped around them.
We run four products and a set of client platforms this way with a small team. This is the anchor post for the series: what agentic engineering is, what actually changed when we moved to it, and where the other posts go deeper.
The three stages
It helps to see it as a progression, because most teams are somewhere on it.
AI-assisted coding. A person is at the keyboard. The AI completes lines, explains code, drafts a function. The person does the task; the AI speeds parts of it up. Most developers are here.
Vibe coding. A person describes what they want, the AI produces it, the person runs it and keeps going if it seems to work. The AI does the task; nobody checks it closely. Fine for prototypes. We explained where it breaks in is vibe coding bad?
Agentic engineering. AI agents take whole tasks: read the spec, look at the code, make the change, run the tests, push. People write the specs, set limits on what agents may do, review the output and decide what ships. The AI does the task; the process checks it.
The difference between the last two isn't the AI. It's the same models. The difference is whether there's engineering around them.
What changed, concretely
When we moved from a person-with-AI to agents-with-limits, five things changed.
The ticket became the unit of work
An agent doesn't have last week's conversation. It has the ticket. So tickets had to become specs: what's wrong, what done looks like, the files involved, how to check it. Writing that takes longer than typing into a chat. It also means the decisions outlive the chat, which turned out to matter more than the speed. Full detail in spec-driven development with AI agents.
Checking the premise became a step
Tickets rot. The code moves after they're written. We measured it on one project: across ten tickets in a night, six were materially wrong or incomplete. One described a fix that was already live. One listed three affected fields where the code had five. One, if built as written, would have double-invoiced real clients.
So when a ticket's premise is uncertain, a read-only scout agent goes first. It reads the code that actually runs, treats "already built" and "already decided" as live possibilities, and comes back with a verdict. Only tickets that come back ready get builder time. Finding that a ticket is wrong is the scout's most valuable output, not a failure.
Limits became the design
More agents isn't more output. We found that out over a weekend in September with six builders running at once: most of the tokens went on branches colliding over shared files and the re-testing that followed. Now:
- at most three builders at a time
- a fixed merge order, rebasing the rest only after each merge
- scoped tests while building; the full suite runs in CI, and CI is the authority
- every agent stops when its useful output is done, builders at "pushed"
- the heaviest review only where the risk is
Every one of those is a limit. Together they're what makes the system cheaper than a person, rather than more expensive.
Review got structural
In a person-led process, review is a habit. In an agent-led one, it has to be a structure, because the volume of code goes up and the author can't be trusted to judge its own work.
Every change is reviewed by a model different from the one that wrote it. Anything touching money, logins, signing or customer data gets an adversarial review on top, from the strongest model we have, with a brief to find a concrete failure case for every finding. We split the two jobs across two vendors so the default review runs on a separate plan. How that works day to day is in reviewing AI-written code that handles money and Codex vs Claude Code.
Shipping stopped being the end
Once agents are producing a lot of merged changes, the thing that breaks is everything downstream: the help article, the marketing page, the changelog. So after a feature merges, another agent reads what changed and writes the follow-up tickets for the marketing site and support docs. Shipping and launching are different days. A feature can sit switched off until the docs, the page and the feature all agree.
What didn't change
People decide what to build. People write the specs and make the product decisions: which exchange rate, whether a setting ships on or off, who sees margin on what. People read the review findings and choose what ships. People own every decision about customers and money.
If anything, those jobs got bigger. When code is cheap, deciding what code to write is most of the work.
What it produces
In a busy week our studio log reports well over a hundred merged changes across our products and client platforms, from a team you could fit around one table. Deploys take about nine minutes, which keeps each change small, which is the size agents build well. The quiet weeks are deliberate: after shipping two money features in Handl in one week, we spent the next on a second pass over them rather than piling on.
The number isn't the AI. It's the system. The AI on its own, with no specs, limits or review, produced the expensive weekend.
Where to start
If you're a team thinking about this:
- Make your tickets good enough that a stranger could build from them. That's most of the work and it pays back whether or not you ever run an agent.
- Run one builder, not five. Add a second when the first is boringly reliable.
- Put a different model on review from the one that builds.
- Decide, in writing, what an agent may never do on its own. Money, emails to customers, deletes, deploys.
- Keep a person at the decision points, and make the decision points explicit.
The principles we work to are written up at how we build, and the week-by-week record of what this produces is the studio log.
FAQ
What is agentic engineering?
Software engineering where AI agents carry out whole tasks, from reading a spec to pushing a tested branch, inside a process where people set the intent, the limits and the review. The agents do the work; the engineering is the structure around them.
How is agentic engineering different from vibe coding?
Both have AI writing the code. In vibe coding nobody checks it closely and the spec lives in a chat. In agentic engineering every task starts from a written spec, runs inside limits, passes tests in CI, gets reviewed by a different model and a person, and ships on purpose.
How is agentic engineering different from AI-assisted coding?
In AI-assisted coding a person does the task and the AI speeds parts of it up. In agentic engineering the agent does the task and the person specifies, limits and reviews.
Do you need a big team to run agentic engineering?
No. It suits small teams best, because the limits keep it affordable and the written specs mean a few people can direct a lot of work. The hard part is the discipline, not the headcount.
If you want software built this way, that's what we do.
 Consulting Inquiries